Team Performance · 20 August 2026 · 5 min read
High Reliability Organisation Principles for Ordinary Businesses
Apply high reliability organisation principles to everyday business: notice weak signals, respect expertise and prepare for recovery without bureaucracy.
Written by Christopher Barber
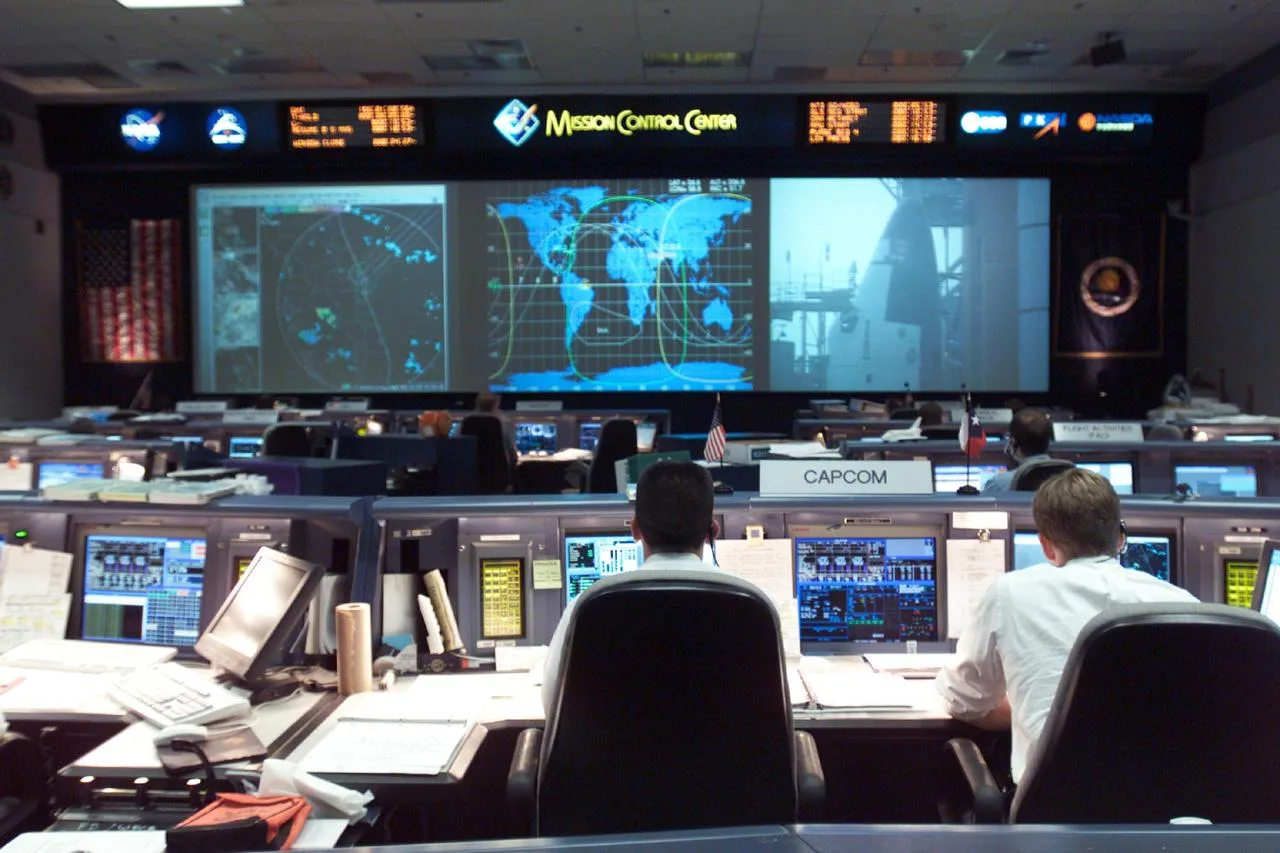
Photograph: Mission Control Center White Flight Control Room views during launch of STS-111 — NASA, public domain
Your business does not need a control room to have work that cannot be allowed to drift. A payroll handover, an access change or a critical customer commitment can depend on several people making compatible decisions. Reliability begins with understanding those connections, not with asking everyone to be more careful.
High reliability organisation principles offer a useful lens for examining work where errors can have serious consequences. For an ordinary business, the sensible approach is selective application. Use the ideas to improve important decisions and handovers, rather than claiming that a checklist has transformed the whole organisation.
Notice small failures before dismissing them
Treat near misses, repeated corrections and workarounds as information. A task completed successfully may still have depended on an unplanned intervention. Ask what nearly went wrong and what prevented it. An outcome recorded as successful can conceal a process that is becoming difficult to operate reliably.
Make reporting proportionate and straightforward. People should know which concerns require immediate escalation and which can go into a routine improvement discussion. If every minor issue demands an elaborate report, the process may become a burden that competes with the very work you want to understand.
Respond to reports with a visible decision. Explain whether you will investigate, monitor or accept the issue for now, and why. Collecting concerns without acting on them creates an archive rather than a learning system. The useful measure is not simply the number of reports but whether important signals receive attention.
Resist the convenient explanation
When a mistake occurs, avoid ending the investigation at human error. A person may indeed have made the wrong choice, but that description does not explain the conditions around it. Examine information quality, workload, interface design, training and the expectations that shaped the choice.
Equally, do not assume every problem requires a complicated theory. The aim is a sufficient explanation that supports useful action. Ask what evidence supports the account and what remains uncertain. Be prepared to revise an initial explanation when the people doing the work provide a different picture.
Look for variations hidden by summary reporting. A department may meet its overall target while one shift or location relies on repeated rescue work. Ask where the process is least stable and which conditions make it harder. Averages are not a substitute for understanding important differences.
Stay close to actual operations
Managers need ways to learn how work happens, not only how procedures describe it. Observe a handover, follow an exception through the system or ask someone to demonstrate a recurring task. The purpose is to understand demands and constraints, not to catch people departing from an idealised script.
Discuss workarounds without automatically endorsing them. Some may reveal a sensible adaptation; others may introduce unacceptable risk. If an official process is impractical, people need a way to raise that problem and obtain an authorised change. Quietly relying on unofficial practice leaves responsibility unclear.
Choose a few indicators that help people act. A growing queue of unresolved exceptions or repeated delays at a dependency may deserve more attention than a polished monthly status. Decide who reviews each signal, what change prompts intervention and what action that person is authorised to take.
Put expertise where decisions happen
Respecting expertise means involving the person who understands the specific problem, even when they are not the most senior person present. It does not mean removing accountability from managers. Establish who contributes technical judgement, who balances wider consequences and who has authority to decide.
Make disagreement usable. Ask the relevant expert to explain the evidence, uncertainty and possible consequences in language the decision owner can understand. Ask the decision owner to state how that advice has influenced the choice. Neither a technical assertion nor a managerial preference should remain beyond examination.
Plan for access to expertise outside normal arrangements. If only one individual can interpret a critical issue, consider documentation, cross-training or an agreed external route. Any alternative should be appropriate to the task; basic familiarity is not a replacement for required professional competence.
Prepare to recover, not just prevent
Prevention deserves attention, but arrangements should also account for disruption. Identify what must continue, what can pause and what would allow work to resume safely. Recovery priorities should be agreed before a team is forced to negotiate them while several stakeholders are demanding immediate service.
Test a bounded failure scenario. Remove a dependency in discussion and ask how the team would respond. Can it locate the right information, establish authority and communicate limits? Keep technical and regulated testing within the relevant procedures. A conversation can reveal gaps without proving that recovery capability is adequate.
- Which critical task currently relies on an informal workaround?
- What early signal would show that its safeguards are weakening?
- Who can stop or change the work if that signal appears?
- What must be checked before normal operation resumes?
Start with one important process
Select a process where a failure would matter and where the team can make practical changes. Map its handovers, exception routes and recovery arrangements. Ask the people involved where they currently compensate for missing information or unclear responsibilities. Use their account to choose a manageable improvement rather than launching a broad campaign.
At the next review, inspect whether that improvement changed the work. Check a real handover or trace an exception from discovery to closure. Reliability is better examined through what people can consistently do than through a statement of aspiration. Begin with the point where the process currently depends on somebody remembering to rescue it.
Bring this to your team
We run NASA-style simulations, astronaut keynotes and leadership expeditions for organisations that need their leaders to make good calls under pressure.
Book a Call